진짜.. AI가 이런것까지 되버리니 저도 만들면서 놀랬습니다..
고정된 영상 하나 뿐이라도 이제 힉스필드의 시댄스 2.5 모델로 얼마든지 멀티 앵글로 만들어 버릴 수 있습니다.
아래 방법을 소개할게요 :)
힉스필드 시댄스 2.5 무료 생성 혜택 받기
https://higgsfield.ai/s/viral-ig-v2-woody_seo-ApmstE
01. 삼각대를 놓고 고정해서 찍은 원본 영상 준비하기
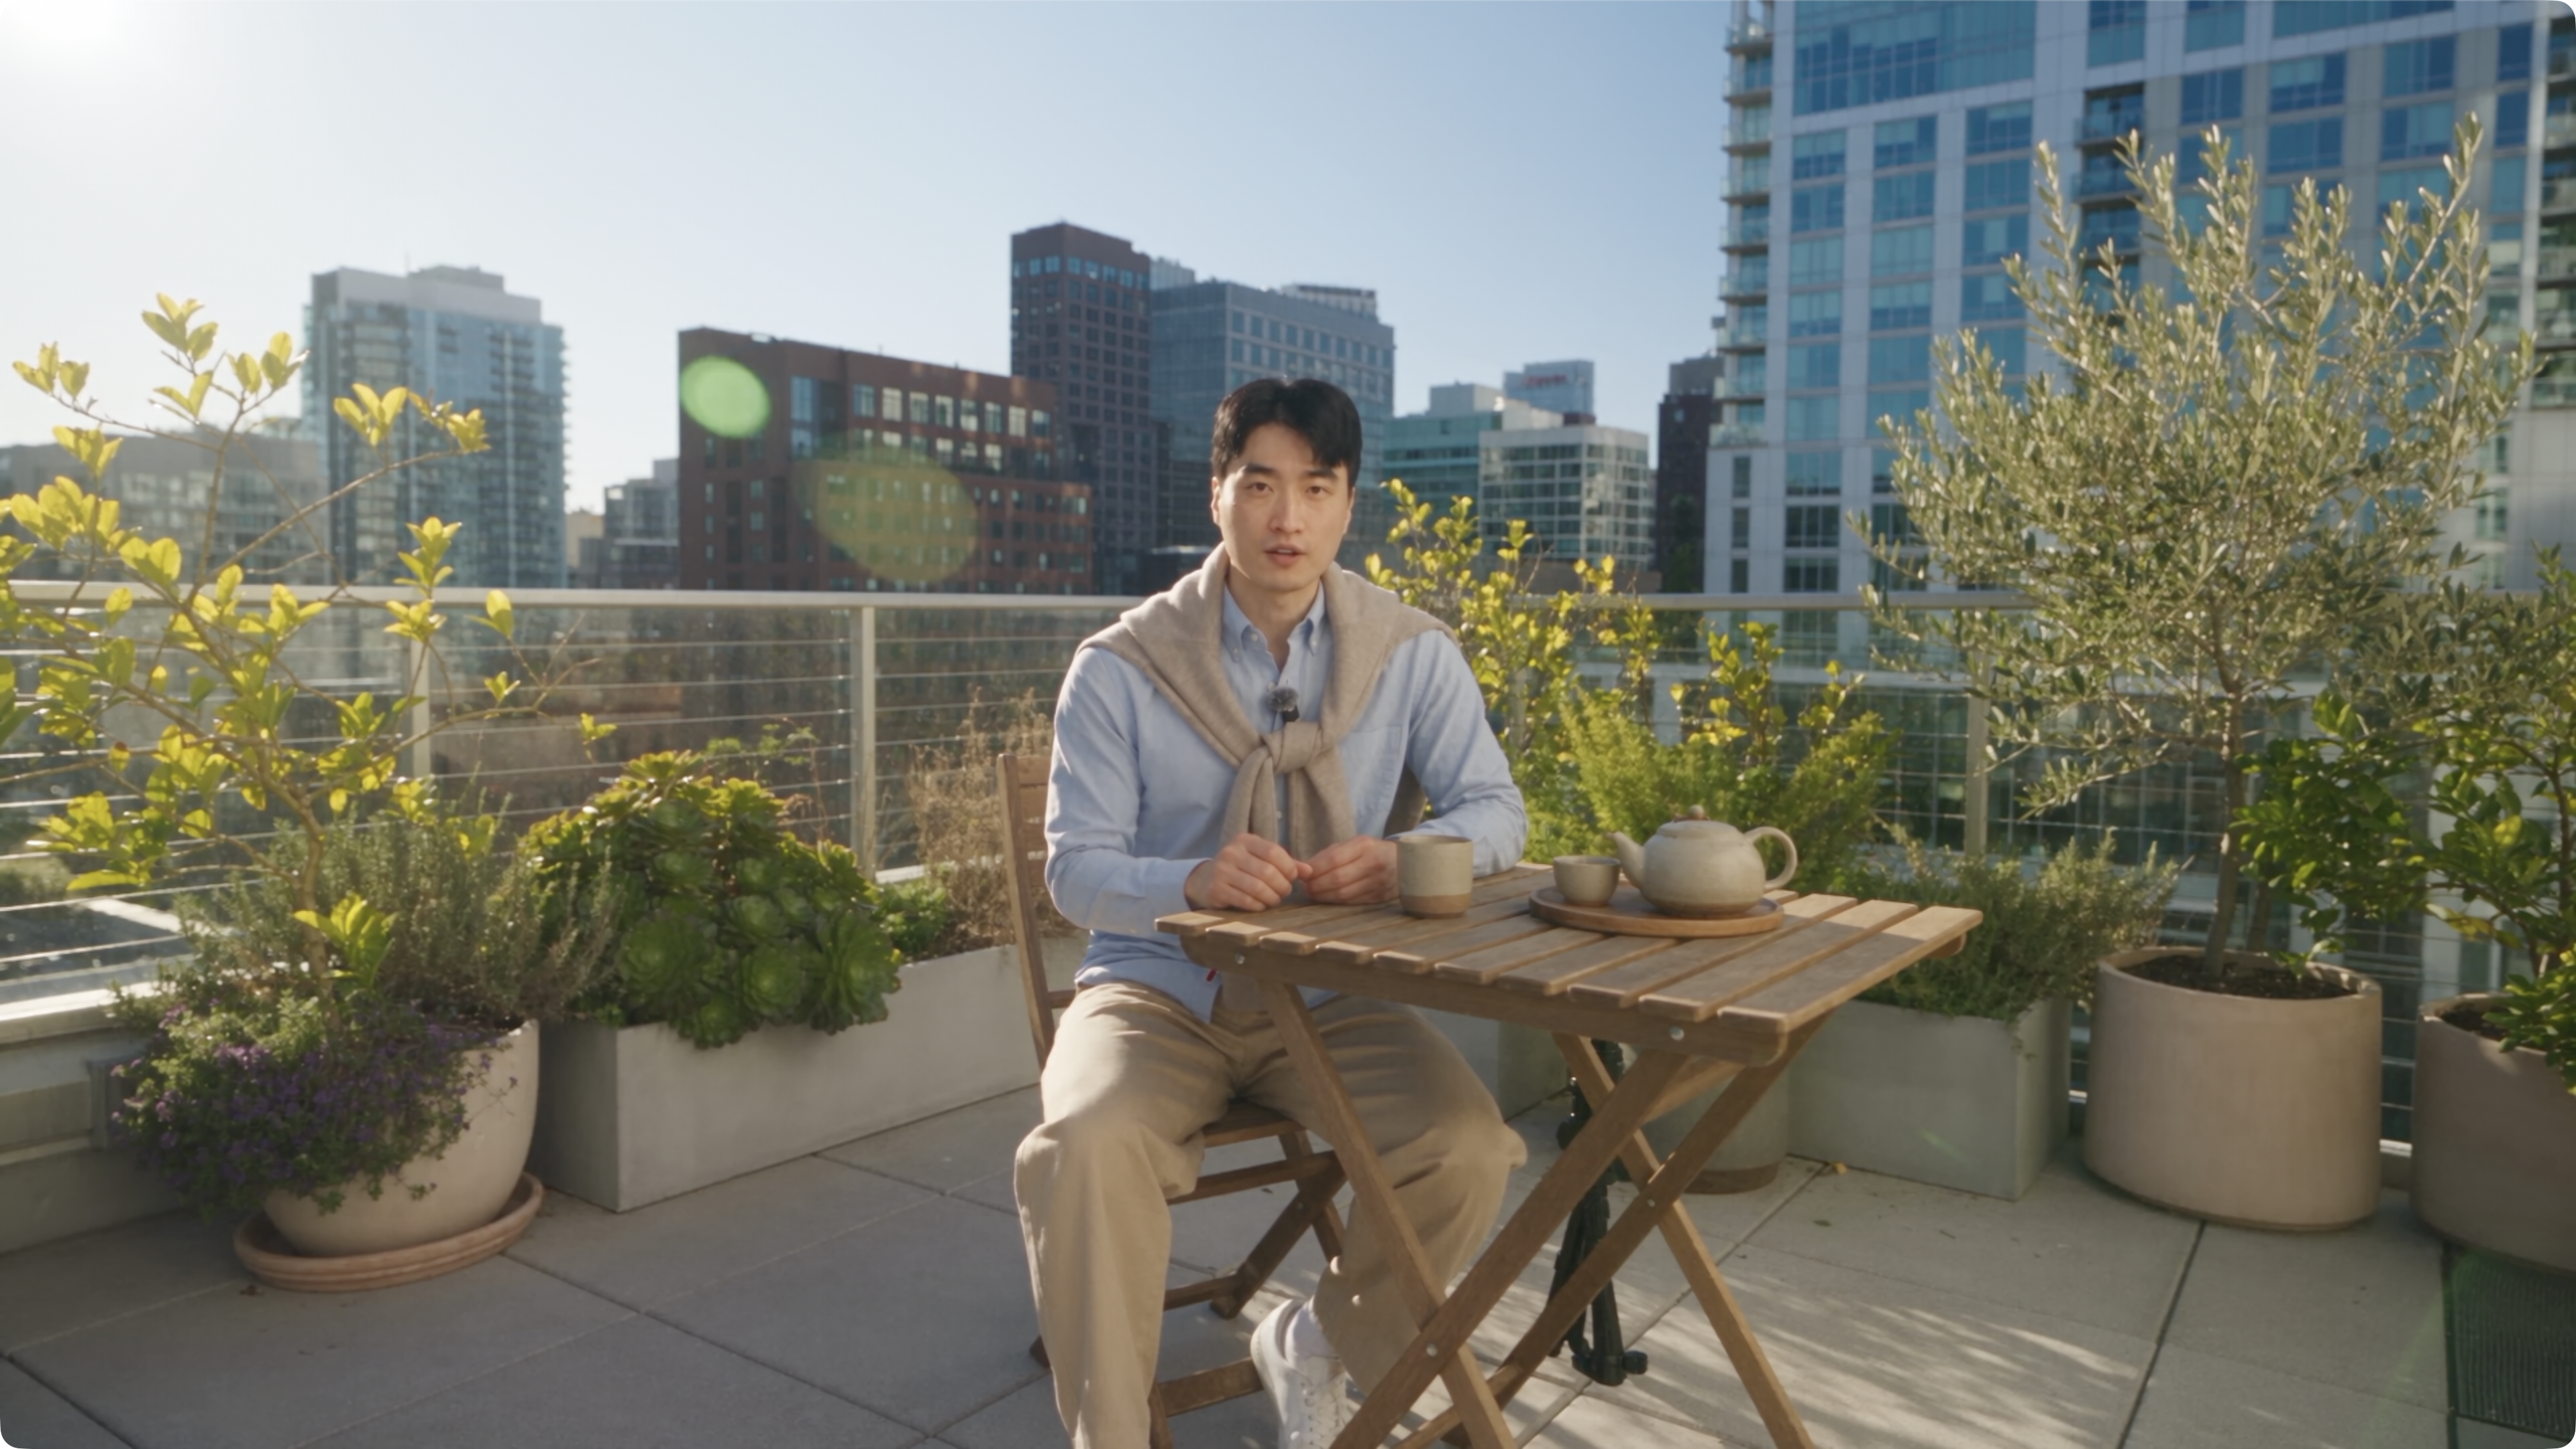
02. 캐릭터 시트 만들기
정면과 측면 사진을 첨부하고 아래 프롬프트를 통해 캐릭터 시트를 만듭니다. (GPT Image2 사용)
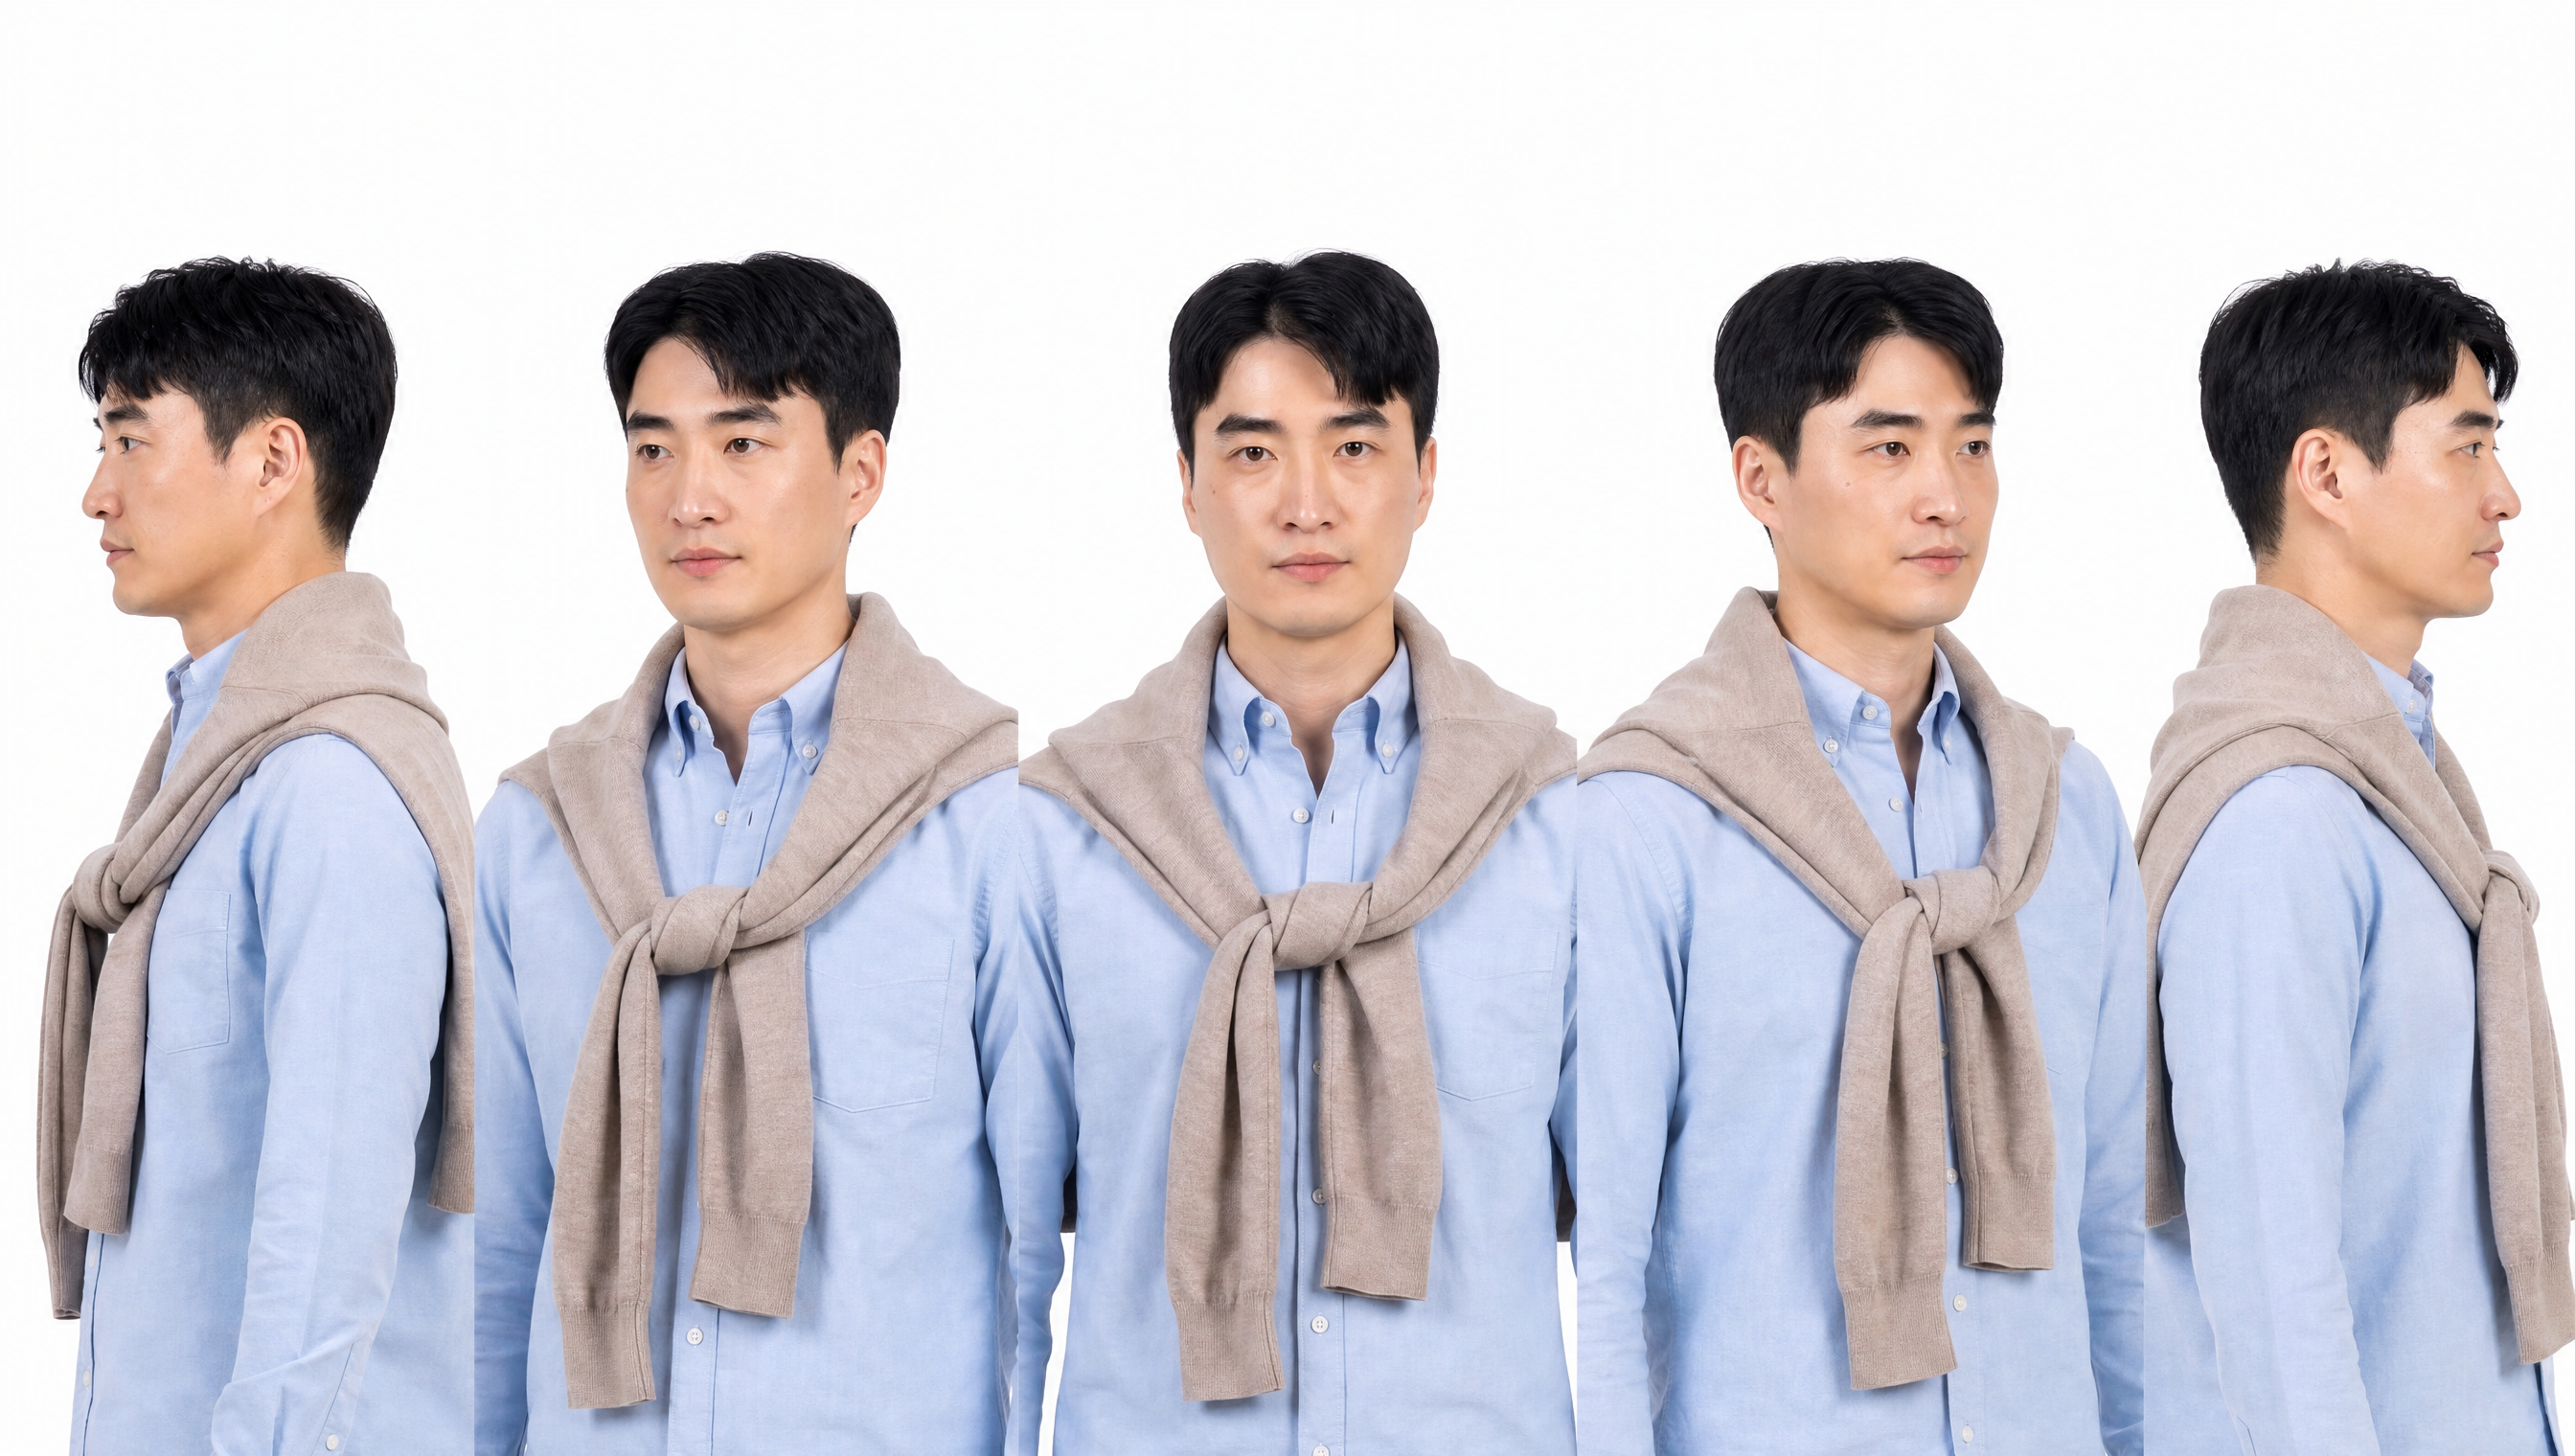
Create a photorealistic character sheet of this person in front of a white studio background. Upper body portraits only. Front view, three quarter view left and right, and both side profiles. Same clothing, same accessories and same hairstyle as in the photo .
03. 시댄스 2.5 멀티캠 기본 템플릿 (Universal Template)
원본 영상과 캐릭터 시트를 힉스필드 시댄스 2.5 모델에 첨부하고 아래 프롬프트로 멀티 앵글을 만들어 보세요.

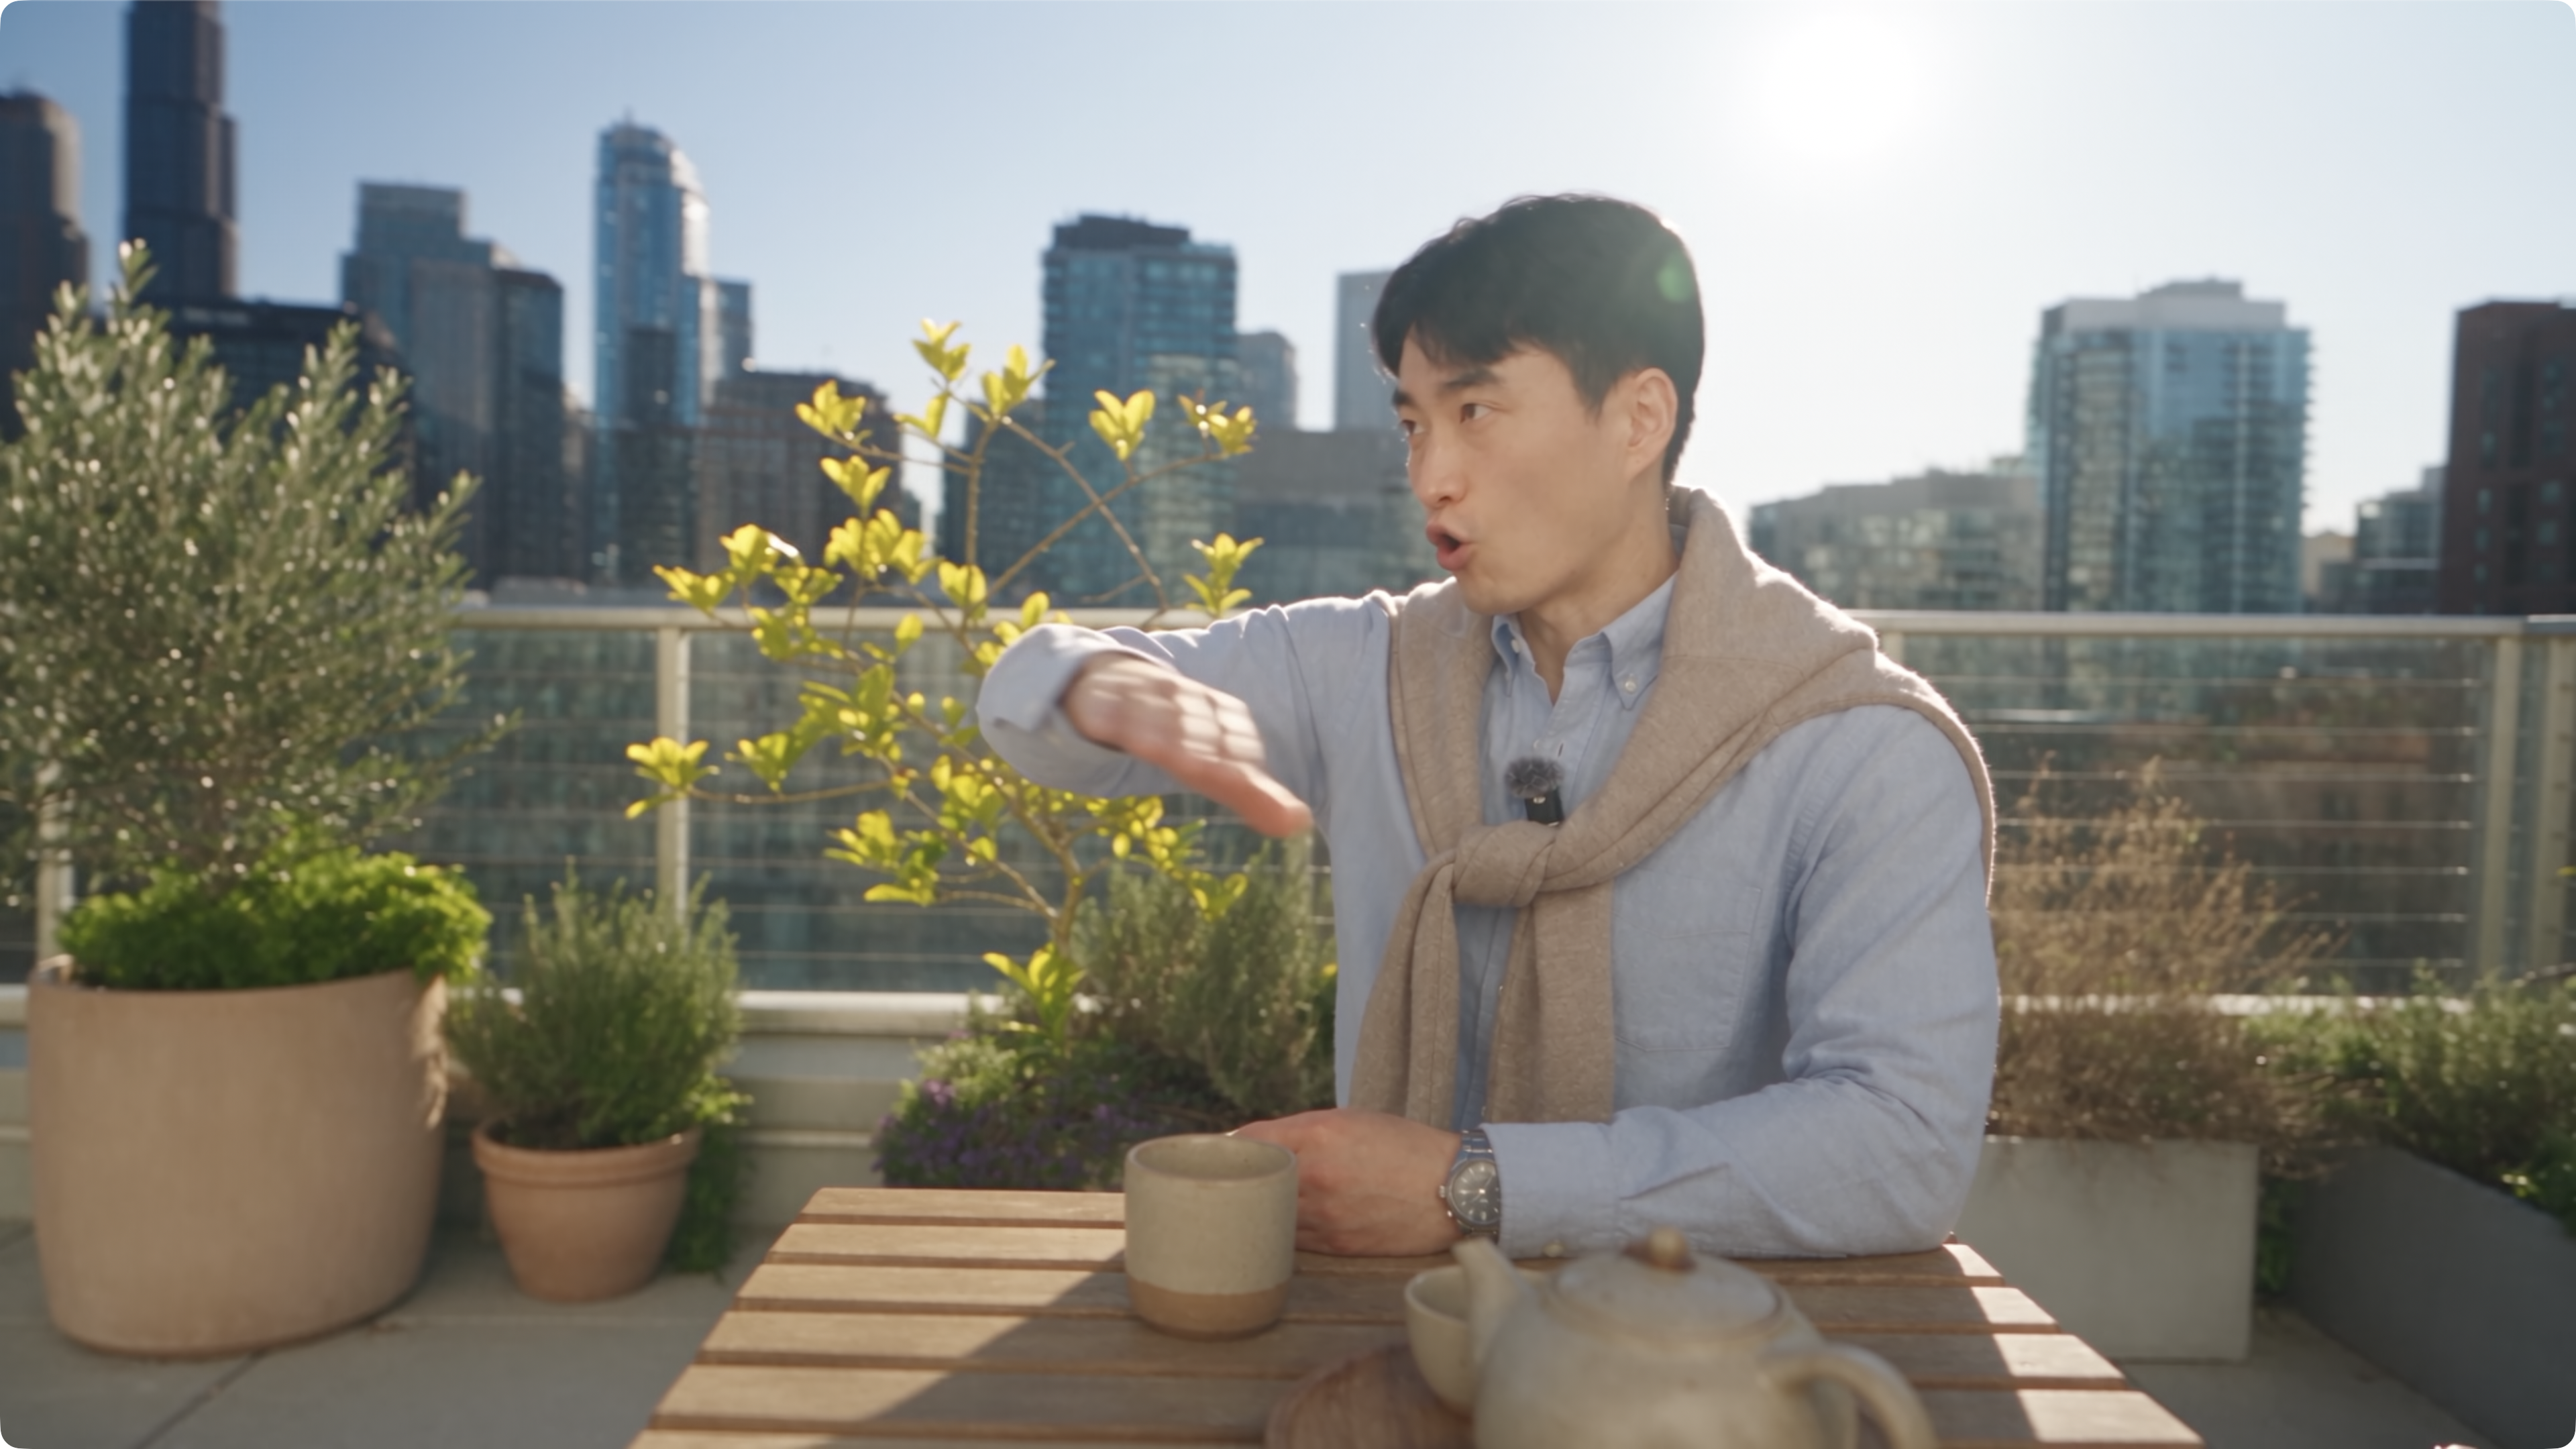
@video1, keep everything the same. Re-shoot this exact clip from one new camera viewpoint. Every movement comes from @video1 and matches it frame for frame: speech, expressions, gestures, body motion. Nothing is re-performed, only the camera is new. Same person, same clothing, same location, same light. Use @image1 only to hold the facial identity from the new viewpoint. SPOKEN WORDS In @video1 they say: "[해당 구간의 실제 대사 입력]". The mouth matches these exact words at their exact original timing. CAMERA [여기에 원하는 앵글 프롬프트 입력] POSITIVE LOCKS The motion mirrors @video1 exactly in timing. Same person, same clothing, same location. Lip sync matches the spoken words. No music. No subtitles. No on-screen text.
[개별 멀티 앵글]
"[해당 구간의 실제 대사 입력]" 구간에 원본 영상의 대사를 입력합니다.
전체를 입력하기 보단, 각 구간마다 싱크를 맞추기 위한 일부 대사를 프롬프트에 넣으면 좋습니다.
앵글 1: 클로즈업 오빗 (Close-up Orbit)
얼굴 중심으로 카메라가 약 60도 천천히 회전하며 배경 보케가 흐르는 시네마틱 클로즈업 샷입니다
@video1, keep everything the same. Re-shoot this exact clip from one new camera viewpoint. Every movement comes from @video1 and matches it frame for frame: speech, expressions, gestures, body motion. Nothing is re-performed, only the camera is new. Same person, same clothing, same location, same light. Use @image1 only to hold the facial identity from the new viewpoint. SPOKEN WORDS In @video1 they say: "[해당 구간의 실제 대사 입력]". The mouth matches these exact words at their exact original timing. CAMERA Tight close-up of the face, slightly below eye level. The camera orbits slowly around them, about 60 degrees across the clip, keeping the face centered and sharp. The background slides behind in soft bokeh. One continuous shot, the camera does not cut on its own. POSITIVE LOCKS The motion mirrors @video1 exactly in timing. Same person, same clothing, same location. Lip sync matches the spoken words. No music. No subtitles. No on-screen text.
앵글 2: 수직 탑다운 (Birds-Eye)
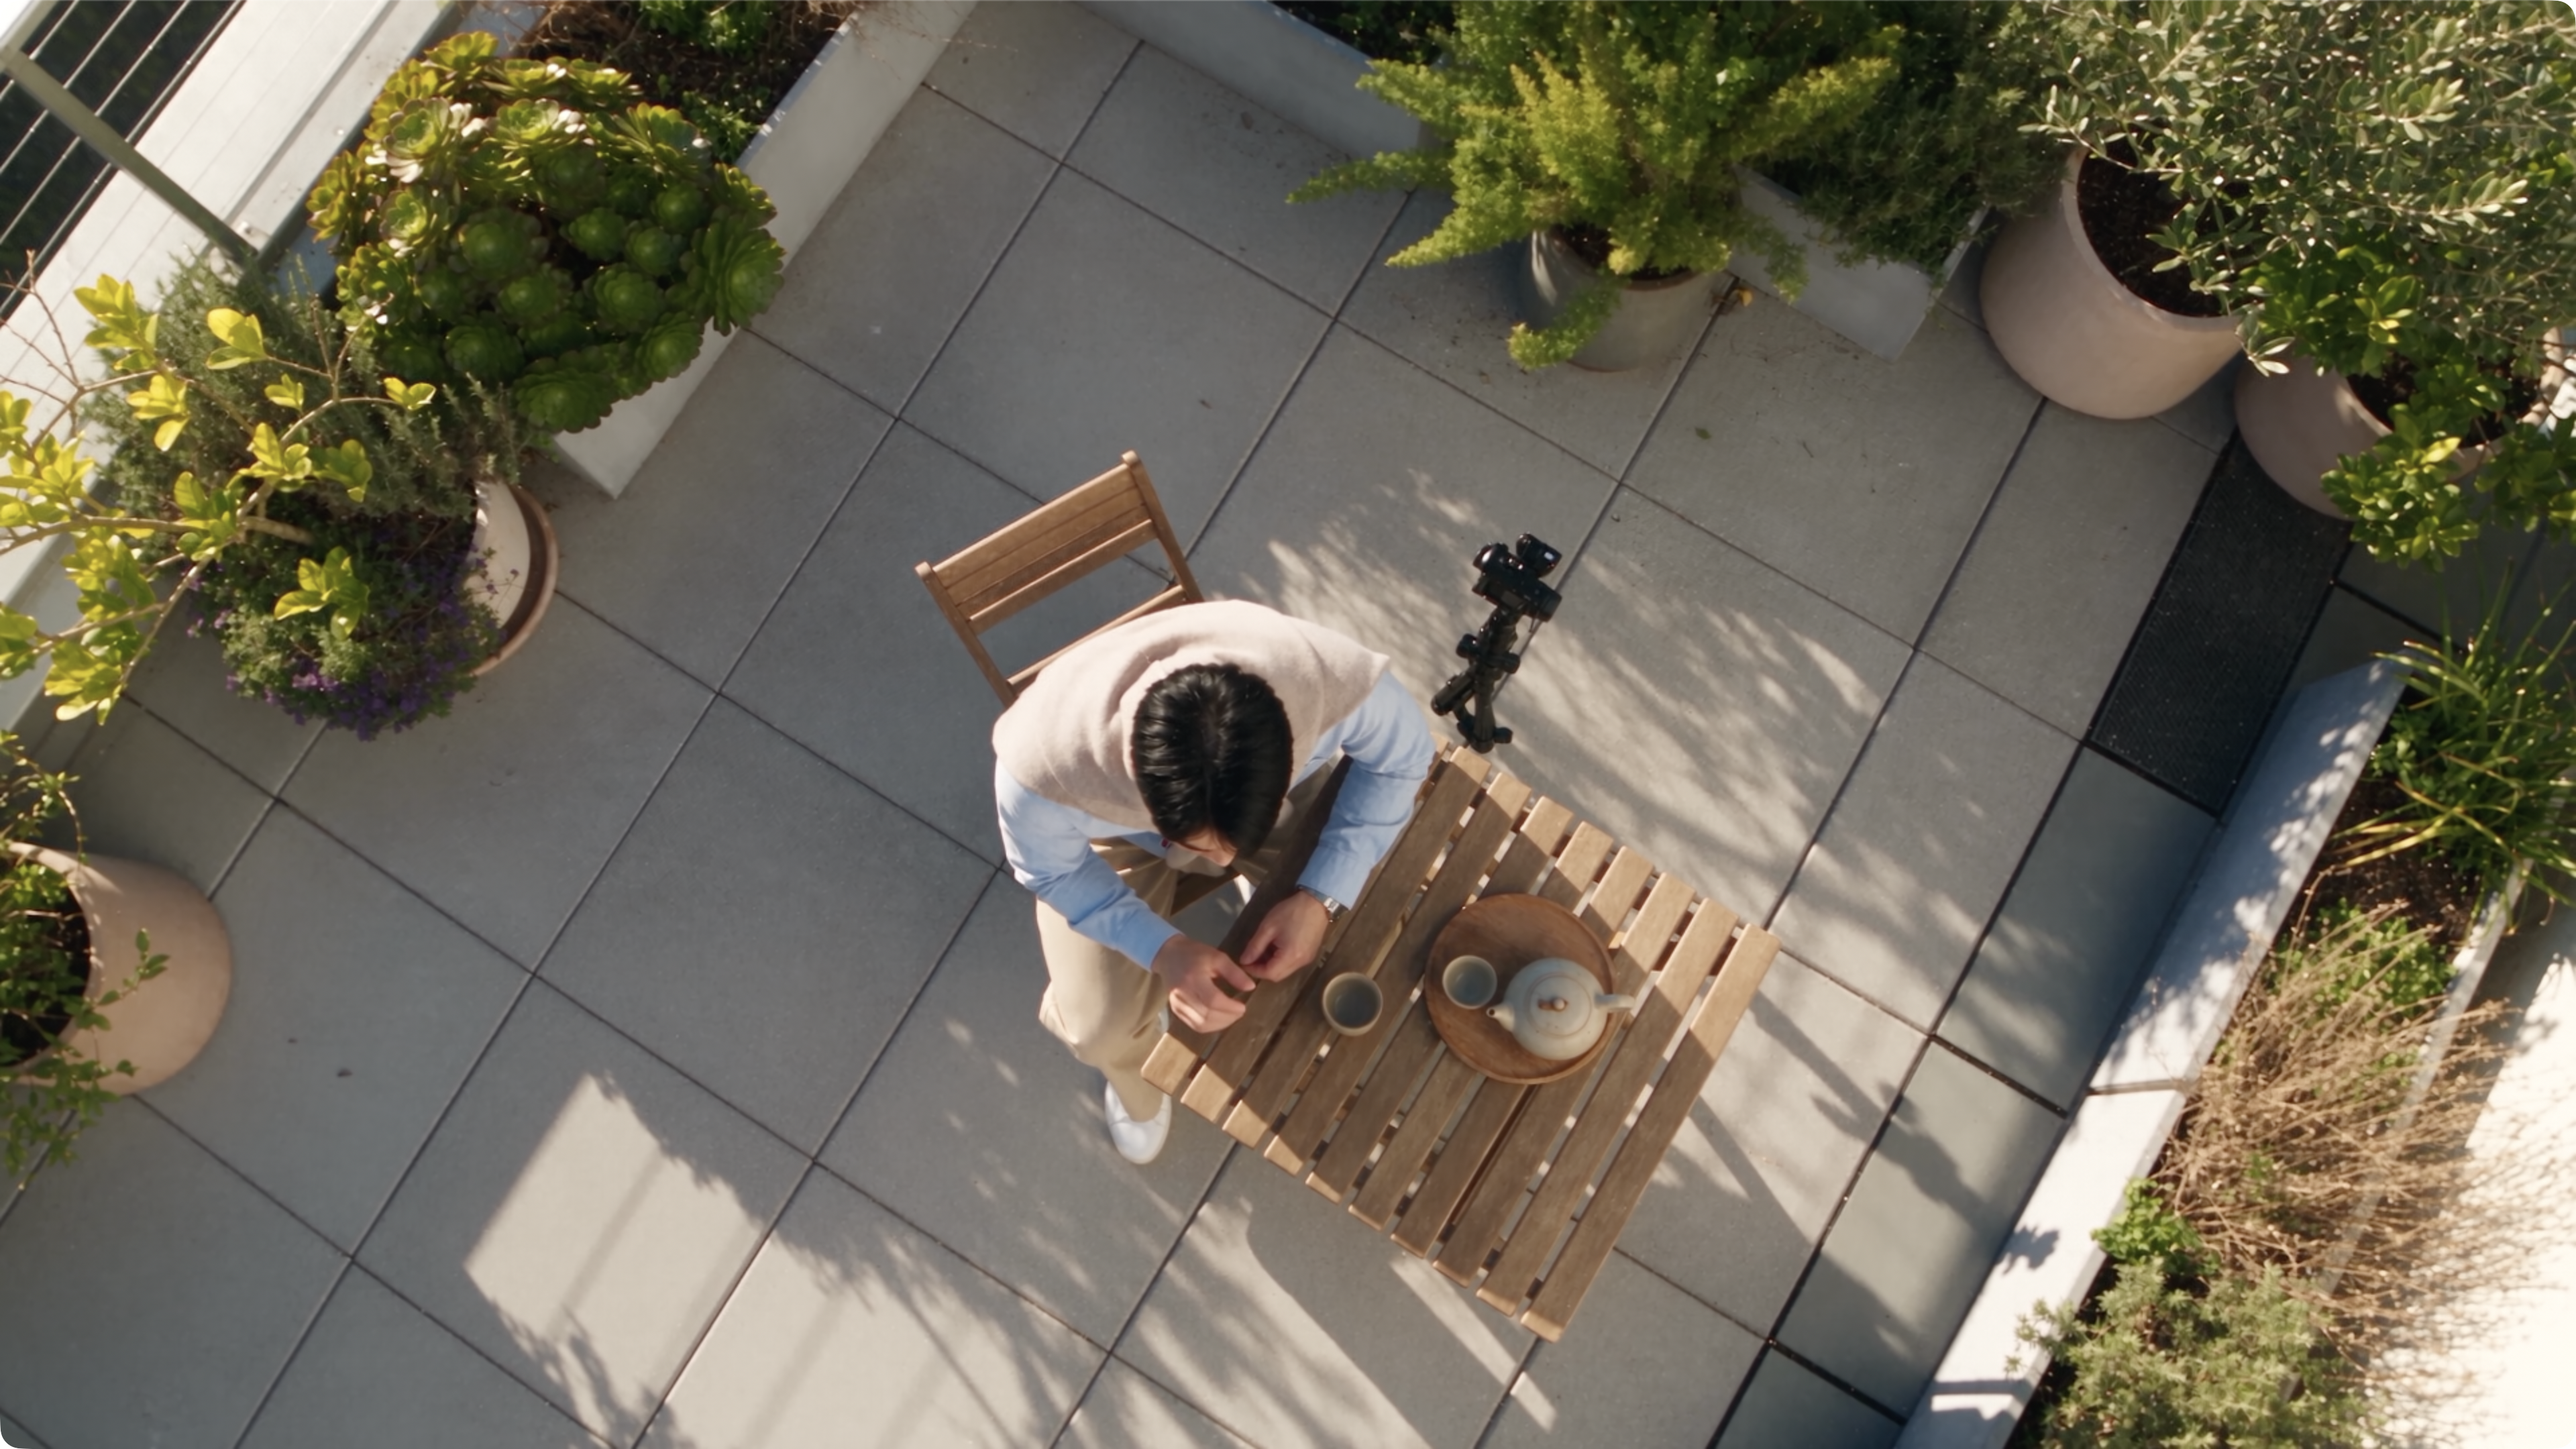
머리 바로 위에서 직각으로 내려다보며 미세하게 다가오는 버드아이 뷰 샷입니다.
@video1, keep everything the same. Re-shoot this exact clip from one new camera viewpoint. Every movement comes from @video1 and matches it frame for frame: speech, expressions, gestures, body motion. Nothing is re-performed, only the camera is new. Same person, same clothing, same location, same light. Use @image1 only to hold the facial identity from the new viewpoint. SPOKEN WORDS In @video1 they say: "[해당 구간의 실제 대사 입력]". The mouth matches these exact words at their exact original timing. CAMERA Birds-eye view for the entire clip, directly overhead, looking straight down. The camera holds the top-down position with a very slow drift closer. One continuous shot, the camera does not cut on its own. POSITIVE LOCKS The motion mirrors @video1 exactly in timing. Same person, same clothing, same location. Lip sync matches the spoken words. No music. No subtitles. No on-screen text.
앵글 3: 시네마틱 드론 (Camera Drone)
높은 각도에서 시작해 서서히 상승하며 멀어져 주변 배경 공간을 넓게 보여주는 드론 샷입니다.
@video1, keep everything the same. Re-shoot this exact clip from one new camera viewpoint. Every movement comes from @video1 and matches it frame for frame: speech, expressions, gestures, body motion. Nothing is re-performed, only the camera is new. Same person, same clothing, same location, same light. Use @image1 only to hold the facial identity from the new viewpoint. SPOKEN WORDS In @video1 they say: "[해당 구간의 실제 대사 입력]". The mouth matches these exact words at their exact original timing. CAMERA Aerial drone shot for the entire clip. The camera starts already elevated, angled down, and climbs steadily higher while pulling away as the location opens up in the frame. Steady glide with a subtle drone sway. One continuous shot, the camera does not cut on its own. POSITIVE LOCKS The motion mirrors @video1 exactly in timing. Same person, same clothing, same location. Lip sync matches the spoken words. No music. No subtitles. No on-screen text.
'AI > AI Tutorials' 카테고리의 다른 글
| [힉스필드 x 챗GPT] / 명령어 모음집 (0) | 2026.09.12 |
|---|---|
| 미쳐버린 AI 자동화… GPT-6 Astra와 일러스트레이터 MCP 세팅법 총정리 (0) | 2026.09.08 |
| 바이럴 영상 따라하기 (0) | 2026.09.03 |
| [Artlist] 아트리스트에 상륙한 차세대 AI 영상 모델 Seedance 2.5로 감성 힐링 영상 만들기 (0) | 2026.08.18 |
| [힉스필드X시댄스2.5 무제한] 사진 한 장으로 만들어지는 제주도 웨딩 스냅 영상 (1) | 2026.08.08 |